Quality engineering for product teams: from critical user journeys and APIs to LLMs and AI agents.
The foundation every product team needs to release with confidence.
For the AI features you're shipping now, which standard QA doesn't know how to test.
Nobody can say with confidence what a release might break. So you test everything by hand, or ship and hope.
The suite fails randomly, people re-run until it's green, and real failures get ignored along with the noise.
The product grows every sprint. Coverage doesn't. Critical journeys break in ways nobody checked.
Your AI feature gives wrong answers with perfect confidence. Users trust it. That's the dangerous kind.
The agent or MCP integration works in the demo, then calls the wrong tool, with the wrong arguments, on real user requests.
Or worse, someone else's. Semantic search looks smart until you measure relevance and check who can see what.
We map your critical journeys, API weaknesses, automation gaps, flaky tests and release risks, then hand you a prioritised plan.
DetailsFor teams that have shipped an AI feature. We test your LLM, RAG, search, agent or MCP integration and show you where it fails.
DetailsWe take your top 20 critical workflows and build a reliable UI and API automation foundation, integrated into CI.
DetailsWe're not a staffing agency and we don't sell testers by the month. We work with your engineers to find the real risks, fix the foundation, and leave behind practices your team can run without us.
Risk-based analysis of your critical journeys, APIs and AI features to surface what's most likely to break, and what it would cost if it did.
Stable UI and API suites and AI eval pipelines wired into CI, so every change is checked and a red build actually means something.
Golden datasets, relevance metrics and calibrated judges, so model, prompt and index changes are measured instead of guessed.
Prioritised findings with severity, reproduction steps and recommended fixes, in language your engineers, product leads and investors understand.
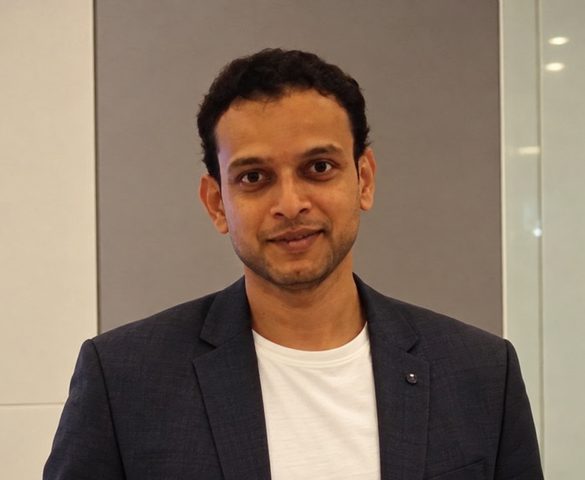
Nethra Tech is led by Avinash, a quality engineer with a career spent on test strategy, automation and team building across web, mobile, API and AI products. Avinash writes and speaks about testing AI systems.
Non-determinism, no single right answer, and failure modes that don't exist in traditional software. Our guide explains how LLM evaluation works in practice.
Read the AI Testing GuideA free 30-minute call. No pitch, just a conversation about what you're building and where it might break.
Book a Free Call